

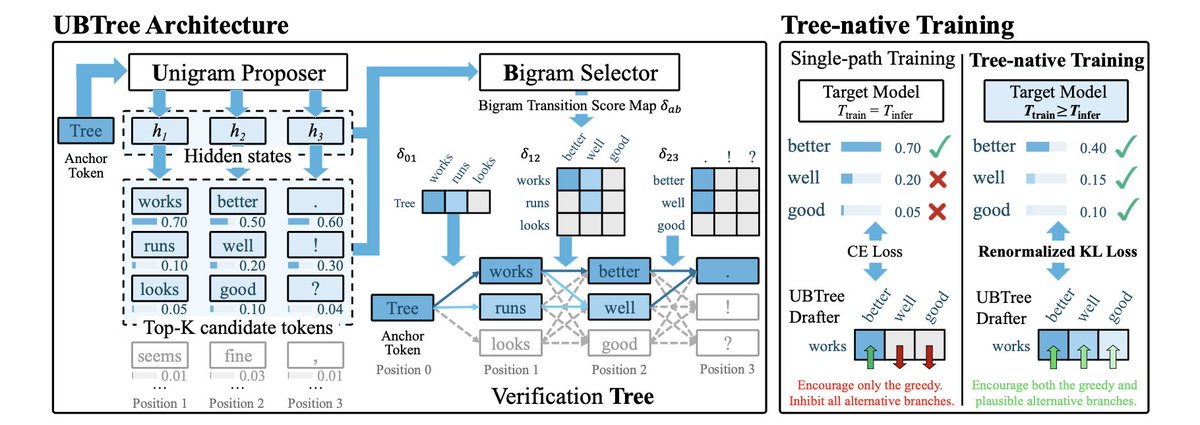
⚡ Introducing UBTree: a frontier dLLM-based method for inference speedup🚀 On Ling3-Flash-124B, UBTree delivers ~1,010 output tokens/s with 4-GPU tensor parallelism (TP4) at concurrency 1, averaging a 3.43× end-to-end speedup over target-only autoregressive decoding across six https://t.co/kUDGUipHzL
Oct 29, 2026
Views8.55k
Comments1
Reposts13