We are excited to announce that we have partnered with @_inception_ai to make Mercury 2 available on Baseten. This makes us the first inference platform to bring Inception’s diffusion LLM to production. Inception’s dLLM architecture fixes the bottlenecks of sequential token https://t.co/DqwV7lc9p7
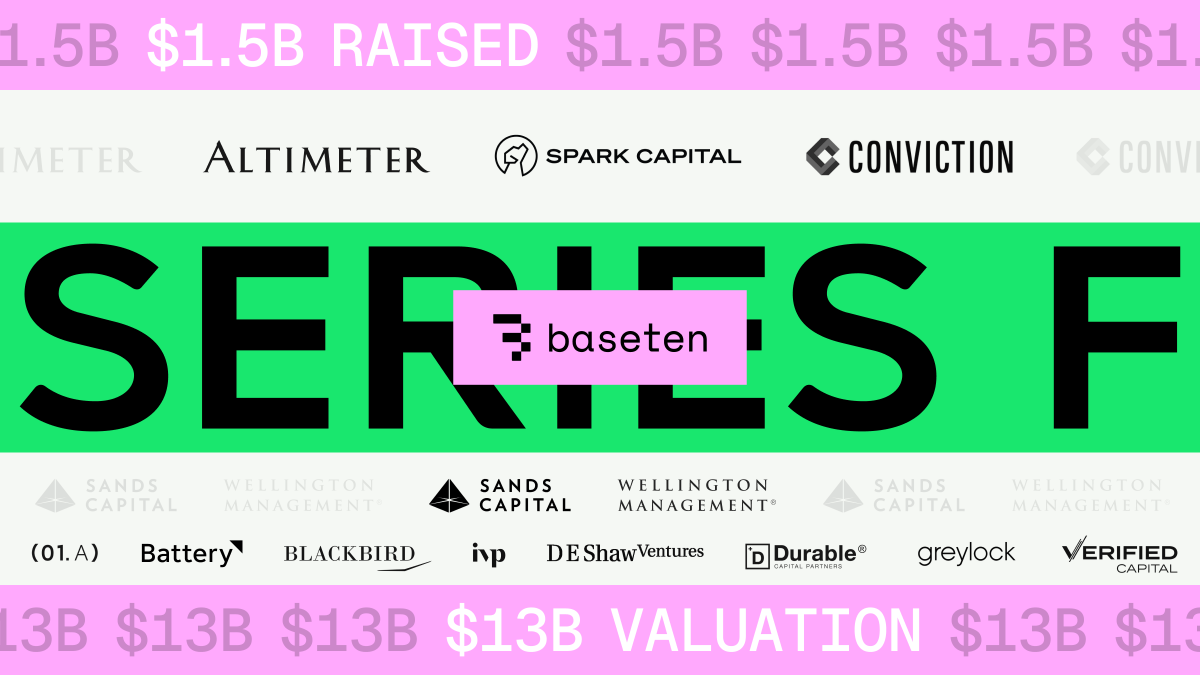
Baseten lands $1.5B Series F

We’re excited to announce our $1.5B Series F. Baseten exists to help companies own their intelligence and run AI products in production with speed, reliability, and control. As we enter this next chapter, three things are clear: 1. Customers like Abridge, Clay, Cursor, Decagon, https://t.co/At1I40iDNc https://t.co/96xCJBjYAh
More from Baseten

Congrats to the MiniMax team on the open-source launch of M3! There are very few <500bn parameter models that can tackle coding, agentic workloads, and multimodal all with a 1M-token context window but M3 does it all. Dig in here: https://t.co/KL4d2rAYPQ https://t.co/57gYFYdfRr
Open models can come from anywhere. Securing them shouldn’t depend on where you get them. Today we're launching Project Beacon to make safety a default for open intelligence. We're partnering with @GoodfireAI to bring inference and in-line monitoring together for the first https://t.co/mymnZqf2xE
We've launched the fastest GLM 5 API available at 190 TPS and 0.79 sec TTFT with the Baseten Inference Stack. Ready for your coding and agentic workflows. https://t.co/iiRmQK3D5U https://t.co/pemMmsGEvb
